Portfolio project: the authority boundary in an automation system
IT Agent Platform
Approval-first automation for modern IT operations
A security-conscious reference implementation for automating repeatable IT workflows. A coordinator routes each request to focused specialist agents, which propose typed actions, while a deterministic policy engine decides which actions require human approval. The default mock executor records what would happen without changing a ticket, identity, endpoint, or production system.
See what is measuredView the repoWhat is not built
- 16 tests passing (latest CI run)
- Mock executor: no real system touched
- Reference implementation, not production
- Approver identity unauthenticated
- No live connector built
01
The problem
Operational automation needs more than a capable model. It needs clear authority boundaries, predictable action schemas, least-privilege integrations, idempotency, and evidence that explains who approved what.
This project was built to practice designing the authority boundary: the line between what a model is allowed to propose and what is actually allowed to touch a ticket, an identity, or an endpoint. The model recommended it and the system did it have to stay two separately auditable steps.
A model approving its own action
Here the model cannot call the approve endpoint, and the API rejects a requester approving their own request, though identity itself is an unauthenticated header.
A policy that trusts the model's label
The policy can raise the model's risk label to a per-operation floor but never lower it, and unknown operations require approval.
02
How it works
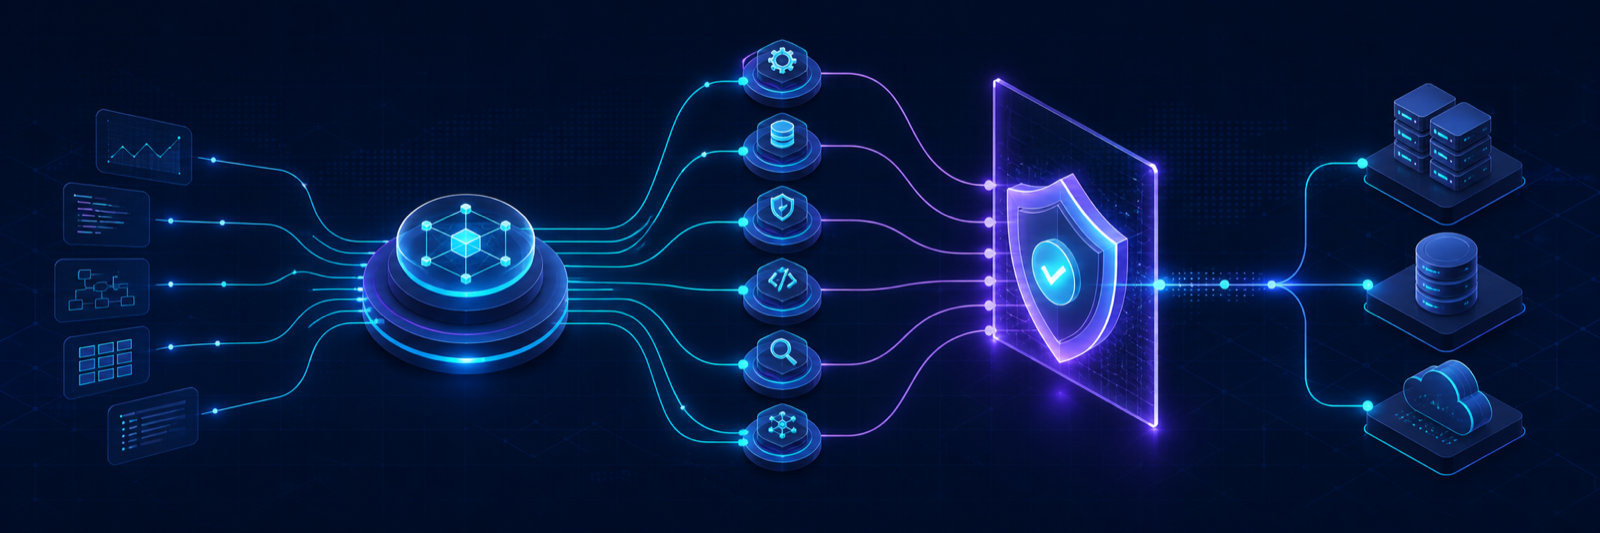
A coordinator routes a request to specialist agents, which propose typed actions. A deterministic policy engine decides which need human approval. Approve and execute are separate, audited steps, and execution goes through a connector that is a no-side-effect mock by default.
Stages, one at a time
Stage 1 The request
An IT request is submitted to POST /v1/workflows.
Stage 2 The coordinator
Coordinator.route picks specialists by keyword match and runs them concurrently with asyncio.gather. The six specialists are Triage, Identity, Incident, Endpoint, Knowledge and Compliance.
Stage 3 Typed proposed actions
Specialists are rule-based by default. In openai mode the model proposes the actions, limited to an allow-list of operations per specialist, and each response is parsed against a strict schema.
Stage 4 The policy engine
ApprovalPolicy.evaluate applies a per-operation minimum kind and risk. Safe local drafts and reads are auto-approved; external-write, privileged, destructive and high-risk actions, and unknown operations, need a different person to approve.
Stage 5 Approve, then execute
AutomationService enforces approve and execute as separate, audited steps. The connector executor is a mock by default, so the response shows "mode": "mock".
Pending and approved actions live in an in-memory dict and are lost on restart.
Stage 6 The audit trail
Workflow, policy, approval and execution events are stored in an ordinary SQLite table.
Not append-only and not tamper-evident.
03
What is measured
This project has no benchmark. The only numbers are its test and coverage figures. The table carries its caveat directly underneath.
The suite covers routing, policy decisions, unauthorized execution, the approval lifecycle, HTTP behavior, audit events, mock execution, and enforcement of model operation allowlists.
| Measure | Value | Source |
|---|---|---|
| Tests passing | 16 on Python 3.9 and 3.12 | latest CI run (pytest --cov) |
| Statement coverage | 93% on a local run (Python 3.14, pytest-cov, 2026-10-06); the latest CI run printed 94% | local pytest-cov run; CI log |
| Branch coverage | not measured | README |
Caveat Statement coverage only. There is no evaluation set or quality benchmark (an evaluation dataset is still on the roadmap), and no connector to a real system exists.
Source: tests/, .github/workflows/ci.yml
04
Architecture pattern
Pattern Governance gate around specialist agents (with a rule-based router and parallel specialists in front).
Routing, the policy table, the self-approval check, execution gating and the audit log are all deterministic. In openai mode the model proposes the actions, limited to an allow-list per specialist, and the policy can raise the model's risk label but never lower it. It governs actions that agents propose; it is not an autonomous loop or a planner.
- IT requestPOST /v1/workflows
- Coordinatorkeyword routing; specialists run concurrently
- Six specialistsTriage, Identity, Incident, Endpoint, Knowledge, Compliance; propose typed actions
- Policy engineOPERATION_FLOORS raises kind and risk; unknown operations need approval
- Human approvala different person than the requester; external, privileged, destructive, high-risk
- Connector executora no-side-effect mock by default
- Audit trailworkflow, policy, approval and execution events in SQLite
05
Competencies demonstrated
Authority-boundary design
Deterministic policy engine, typed action taxonomy, per-agent operation allowlists: the model proposes, the policy decides.
Separation of duties
The API rejects a requester approving their own request (identity is self-asserted; see not built).
Multi-agent coordination
Deterministic routing with concurrent specialist analysis.
Safe defaults
Runs without external credentials; the default mock executor records what would happen without side effects.
Developer experience
FastAPI, interactive OpenAPI docs, Docker, Ruff, pytest, and GitHub Actions.
06
What is not built or not verified yet
Taken from the repository's own Known limitations and Production readiness list. It describes itself as a reference implementation, not a safe control plane. This is part of the pitch.
- not built
Authenticated identity
Approver identity is unauthenticated. The API rejects approval when the approver matches the requester, but both are self-asserted. There is no authentication, role check, or approver allowlist.
- not built
A live executor
IT_AGENT_EXECUTION_MODE=livedoes nothing: the setting is parsed but never read, and there is no live executor. - limit
Approved actions are held in memory
Pending and approved actions are lost on restart; only audit events persist in SQLite.
- limit
Audit log is not append-only or tamper-evident
It is an ordinary SQLite table; rows can be updated or deleted by anyone with database access, and there is no hash chain.
- limit
Approvals do not expire and are not bound to arguments
An approval is a status flip with no TTL, not tied to a hash of the action's operation and arguments.
- limit
Idempotency keys are not enforced
Keys are generated and passed to the executor, but nothing deduplicates on them.
- limit
Operation floors are a static table
Hand-maintained and covering operation names only, not arguments or targets.
- not built
Budget or cost controls
There is no token, spend, or rate limit on OpenAI-mode analysis.
07
Roadmap
- Not doneDurable workflow and action state
- Not doneSSO/JWT authentication and role-based authorization
- Not doneServiceNow or Jira Service Management sandbox connector
- Not doneMicrosoft Entra ID or Okta sandbox connector
- Not doneMetrics, traces, and operational dashboards
- Not doneEvaluation dataset and quality gates
- Not doneDeployment templates for a managed container platform